



Reson8 released Rumble-2-Flash on November 18, 2026 as an Apache 2.0 open-weight speech recognition model with 0.5 billion parameters, 40+ languages, and native Hugging Face Transformers and vLLM paths. The Hugging Face blog and Reson8 announcement pitch it as competing with models 3× to 60× larger on Open ASR Leaderboard tasks while keeping no custom runtime fork.
What shipped
| Piece | Detail (per Reson8 / HF) |
|---|---|
| Weights | Reson8/Rumble-2-Flash on Hugging Face |
| License | Apache 2.0 |
| Stack | Qwen3-ASR architecture; on-policy distillation from Rumble-2 |
| Inference | Transformers AutoModelForMultimodalLM; vLLM audio chat API |
| Languages | 40+ with optional forced language or auto detect |
Reson8 had already exposed an API tier in early November; November 18 is the open-weight drop SiliconANGLE and TLDR also flagged.
Quickstart (Transformers)
Reson8's documented Python path:
from transformers import AutoProcessor, AutoModelForMultimodalLM

model_id = "Reson8/Rumble-2-Flash"
processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForMultimodalLM.from_pretrained(model_id, device_map="auto")

inputs = processor.apply_transcription_request(
    audio="path_or_url.wav",
    language="English",
).to(model.device, dtype=model.dtype)

output = model.generate(**inputs, max_new_tokens=512)
generated = output[:, inputs["input_ids"].shape[-1]:]
print(processor.decode(generated, return_format="transcription_only")[0])
That pattern matters for teams tired of trust_remote_code speech stacks—Rumble-2-Flash targets day-zero compatibility like other Qwen3-ASR-family tools explainx.ai covered in Qwen38 harness posts.
Benchmarks Reson8 claims—and how to verify
Reson8 publishes Open ASR Leaderboard runs on H200 + vLLM:
- ~6.6% average English WER across public splits
- Multilingual averages near 7% on listed European and Hindi sets
- >7,000 RTFx throughput when batches stay full
For messy telephony, Reson8 cites AppTek's 302-hour call benchmark at ~7.86% WER, comparing to NVIDIA Nemotron 3.5 Transcribe (30B) at 7.78% in its table—useful if you build call-center analytics, not only podcast cleanup.
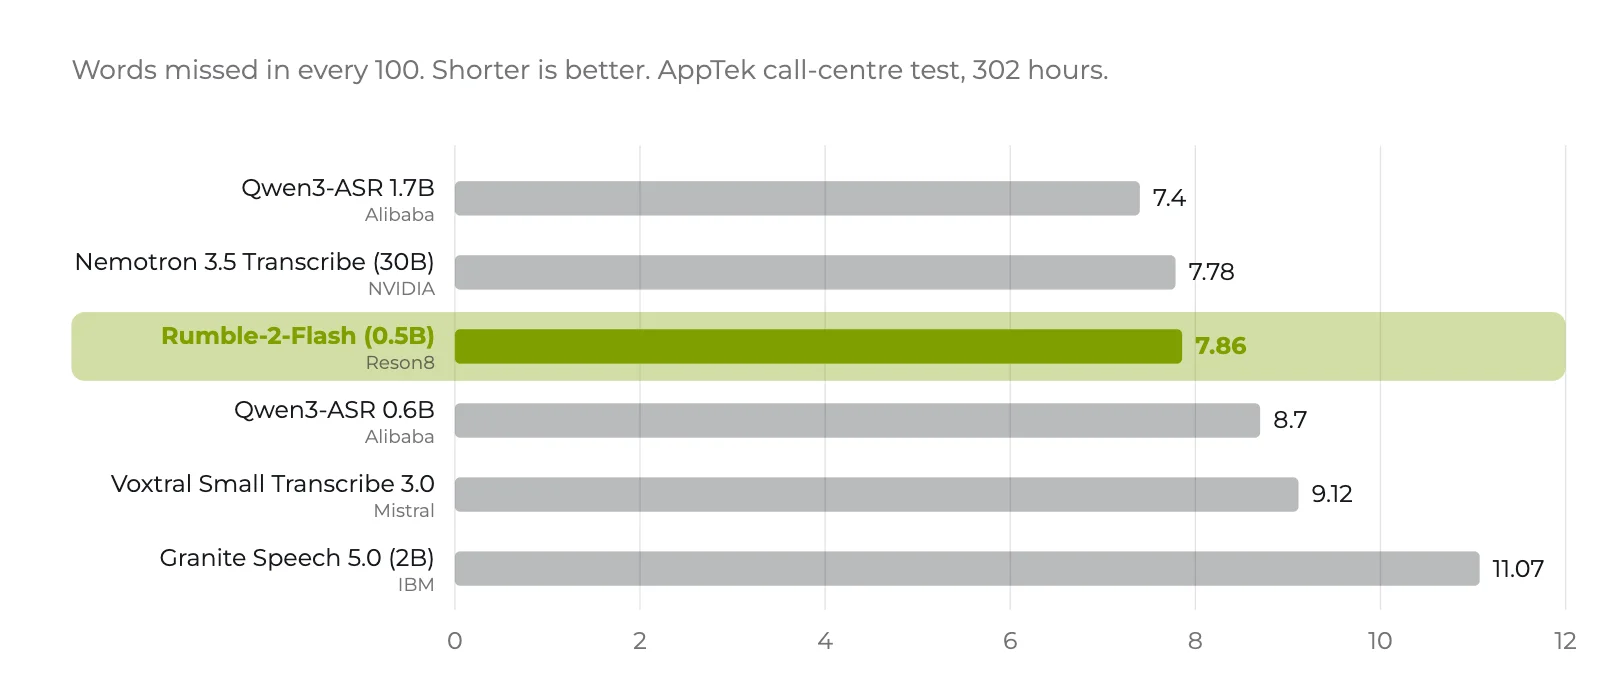 AppTek call-center WER benchmark chart comparing Rumble-2-Flash to larger ASR models
Image: Reson8
Treat vendor tables as hypotheses. Run your audio through Whisper baselines and Rumble-2-Flash on the same hardware before switching production routes.
When to pick Rumble-2-Flash
| Use case | Fit |
|---|---|
| Multilingual batch transcription on a budget GPU | Strong candidate if WER holds |
| Real-time phone audio | Check call-center numbers on your accents |
| Custom vocabulary at scale | Reson8 still reserves 50k custom terms to paid Rumble-2 API per its blog |
| On-device | 0.5B may fit edge boxes where mobile SLM factories already run |
How on-policy distillation differs from ordinary ASR training
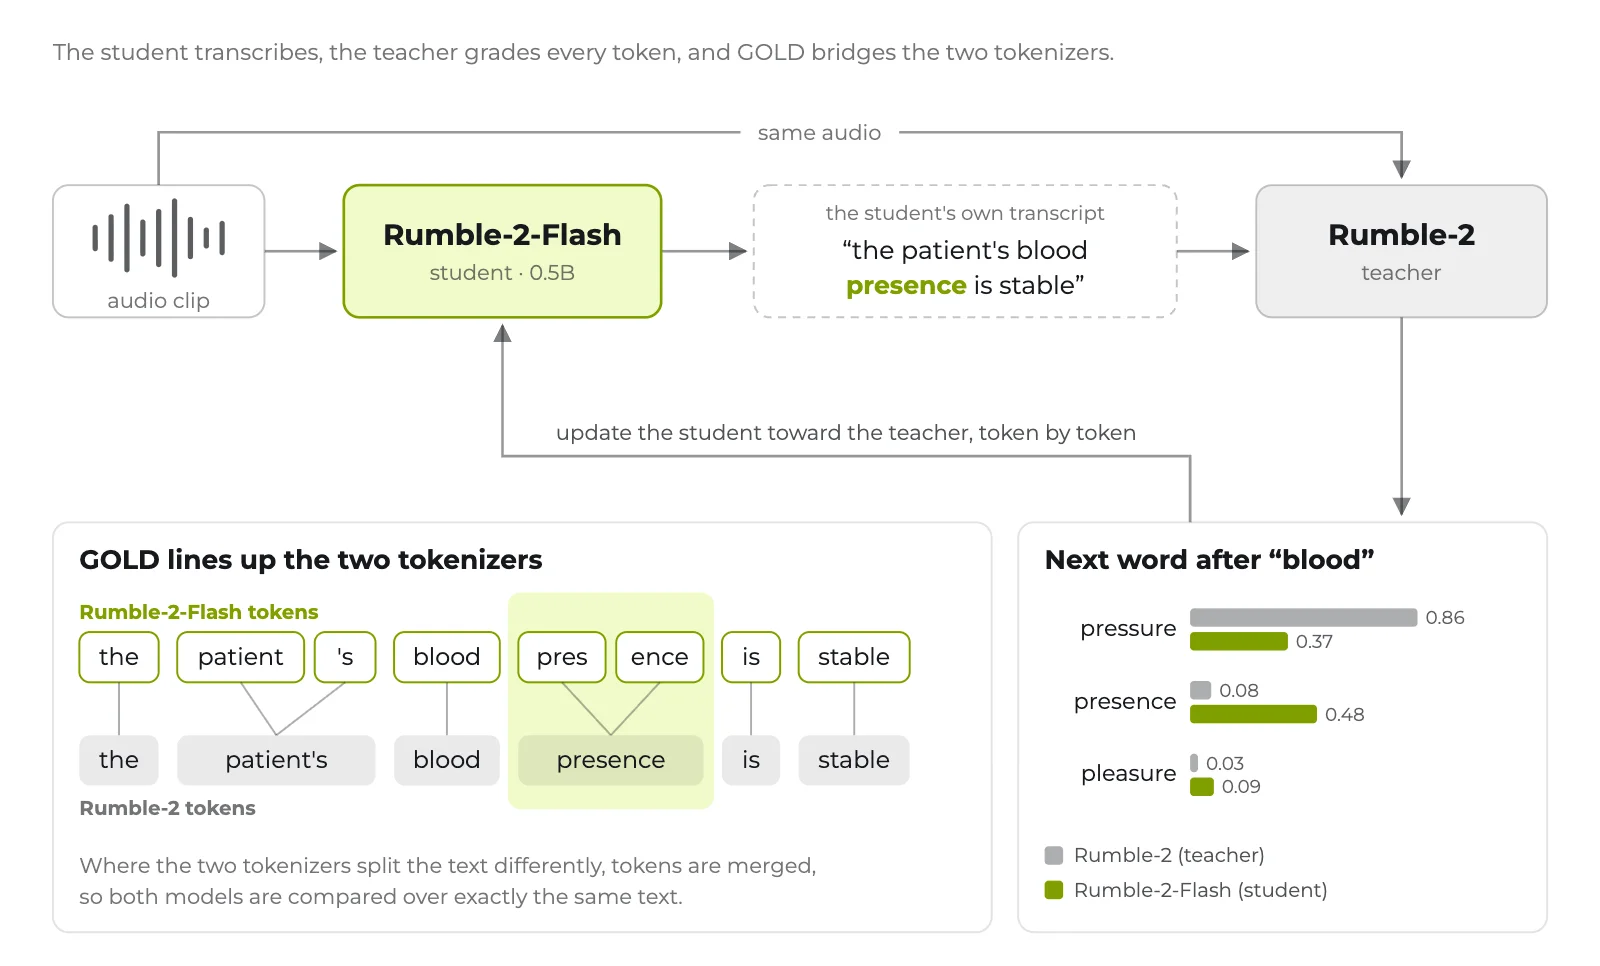 On-policy GOLD distillation diagram from Rumble-2 teacher to Rumble-2-Flash student
Image: Reson8
Reson8's Hugging Face post stresses on-policy distillation with GOLD to bridge tokenizer differences between teacher Rumble-2 and student Rumble-2-Flash. Plainly: the student generates transcripts, the teacher grades token-by-token, rather than training only on static teacher labels.
That matters because speech errors are structured—substitutions, dropped fillers, numeral formatting—and because small models overfit quickly on clean audiobook data then fail on noisy operational audio or call-center noise. Reson8 claims phone-call robustness specifically because distillation saw teacher behavior on hard audio.
Builders comparing NVIDIA Nemotron science agents or Shanghai AI Lab Sage agents should still treat ASR as its own benchmark lane—WER on your domain beats parameter count.
Open ASR Leaderboard numbers Reson8 published
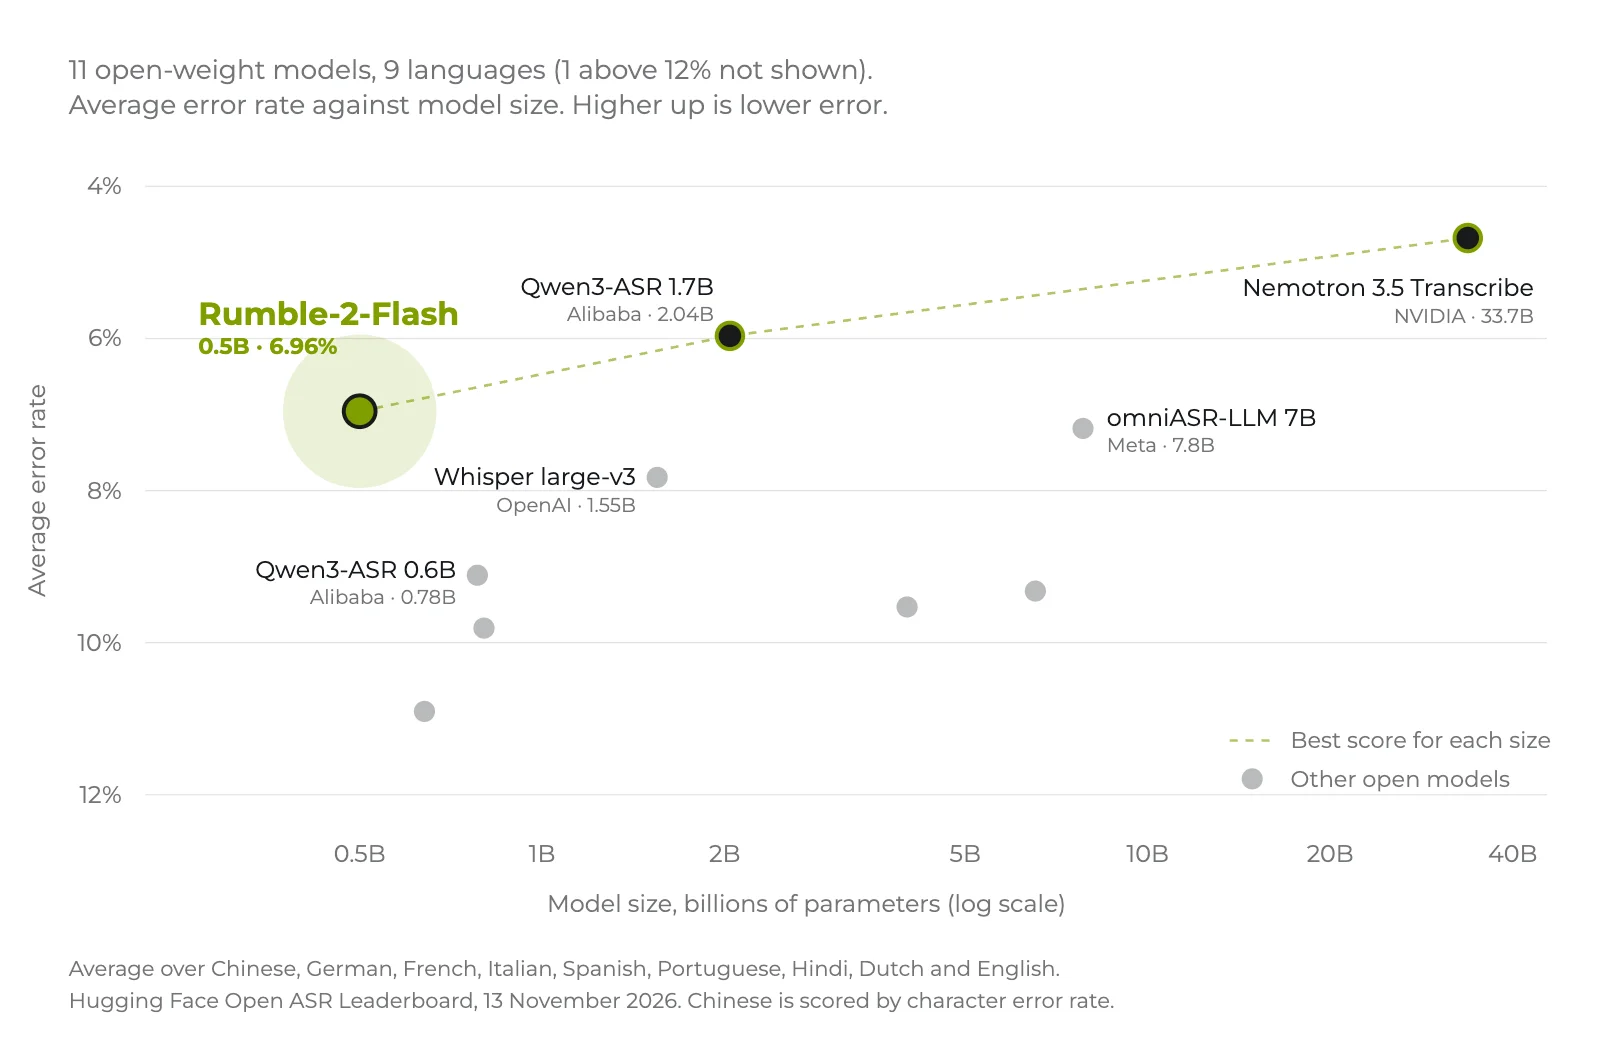 Open ASR Leaderboard chart of model size versus multilingual word error rate
Image: Reson8
Reson8 attached leaderboard release 18-11-2026 (v1.16.1) numbers on H200 + vLLM. Highlights from the model card:
| English split (examples) | WER % | RTFx (where listed) |
|---|---|---|
| SPGISpeech | 3.08 | 7308 |
| VoxPopuli | 2.43 | 4222 |
| Earnings22 | 6.45 | 4811 |
| Private conversational | 13.14 | (aggregated) |
Multilingual track averages near 6.96% across Chinese, German, French, Italian, Spanish, Portuguese, Hindi, Dutch, English in Reson8's blog—better than Meta omniASR-LLM 7B in their table, ahead of Whisper large-v3 on that snapshot.
Caveat: Leaderboard audio is curated. Your Zoom, Discord, or PSTN trunks may invert rankings. Budget a day to replicate runs before ripping out ElevenLabs voice stacks or cloud STT APIs.
vLLM deployment sketch
For teams already standardizing on SageMaker KV-aware routing or vLLM Rubin claims:
uv pip install "vllm[audio]" openai
vllm serve Reson8/Rumble-2-Flash --max-model-len 4096
Then hit the OpenAI-compatible endpoint with base64 WAV payloads per Reson8 docs. Temperature 0 is recommended for deterministic transcripts.
Watch batch sizing: Reson8's 7,000+ RTFx figure assumes full batches on long corpora—interactive mic streaming will sit far lower. Plan GPU count using your concurrency, not leaderboard peak.
API pricing versus self-hosting
Reson8's product blog markets €0.01 per hour of audio at entry tiers—€10 per thousand hours—for API users, while November 18 adds free weights. Economics:
| Mode | When it wins |
|---|---|
| Self-host Apache weights | Steady high volume, existing GPU fleet, data residency needs |
| Reson8 API | Spiky workloads, no ops, quick prototypes |
| Rumble-2 paid tier | Needs 50k custom vocabulary without fine-tune |
Pair cost math with RightNow kernel API pricing discipline—open weights shifted LLM markets; speech may follow if 0.5B quality holds on calls.
Comparisons readers search for
Versus OpenAI Whisper: Reson8 claims leaderboard beats on listed English and multilingual splits. Whisper remains the default fine-tune base in many repos; Rumble-2-Flash targets teams who want Qwen3-ASR-native tooling without Whisper's older encoder stack.
Versus Qwen3-ASR sizes: Reson8 compares to Qwen3-ASR 0.6B and 1.7B on AppTek calls—positions 0.5B between them on phone WER.
Versus NVIDIA Nemotron 3.5 Transcribe (30B): Near-parity on call-center WER at ~60× fewer parameters in Reson8's marketing—if true on your calls, CapEx for transcription farms drops sharply.
Integration with agent pipelines
Speech is re-entering agent loops via Gemini Tasks payments and Copilot voice surfaces. A local 0.5B transcriber can front tool-calling LLMs:
- Transcribe meeting off-cloud
- Pass text to MCP hosts or Power BI plugins
- Redact before frontier APIs if disclosure rules apply
Latency tip: Run VAD + chunking before batching to approach Reson8's throughput claims without blocking interactive agents.
Limitations Reson8 admits
The product blog notes ~9 in 10 words in noisy meetings—honest hedging. Custom vocabulary still lives on Rumble-2. Downloads on Hugging Face were hundreds, not millions, at publish—early adopter stage.
None of that blocks a pilot. It defines pilot scope: batch archival transcription, not mission-critical live captioning, until you validate.
Licensing and compliance notes
Apache 2.0 on weights is enterprise-friendly, but:
- Training data lineage is Reson8's statement, not your audit until model card review completes
- Biometric laws still apply to voice in EU/UK contexts—see Gallup companion sentiment for consumer optics, not legal advice
- Call recording consent rules dominate deployment, not WER
Document residency: self-hosting fixes many SaaS DPAs headaches compared with mystery cloud STT.
Extended FAQ: what searchers ask about small ASR models
Is Rumble-2-Flash better than Whisper for podcasts? Reson8's clean read speech WER near 2% on some splits is promising; podcasts with music beds need your own eval.
Can I fine-tune Rumble-2-Flash? Apache weights allow fine-tune experiments; Reson8 still pitches Rumble-2 when you want massive custom vocab without training.
Does it run on Apple Silicon? Transformers device_map="auto" typically routes to MPS when available; validate real-time factor—0.5B is small but audio preprocessing still costs CPU.
Will Hugging Face Inference Providers host it? The model card noted no default inference provider at publish—plan self-host or Reson8 API.
How does this relate to MiniMax music video tools? Different modality—see Suno Visuals / MiniMax for generative video, not ASR.
What about keyword spotting versus full transcription? At 0.5B, full phrase transcription is the point; wake-word systems may still prefer tiny specialized models.
Error handling for live agents: Wrap generate calls with timeouts and fallback to human when WER spikes on unknown accents—especially if you serve inclusion healthcare benchmarks populations underrepresented in leaderboard splits.
Hardware planning table
| Hardware | Rough expectation (not a guarantee) |
|---|---|
| 1× consumer GPU (8–12 GB) | Batch offline files; tight for large concurrent streams |
| H200 class (Reson8 bench) | Leaderboard-scale throughput numbers |
| CPU-only | Possible for short clips; test before promising SLAs |
Combine with 192GB local AI guide thinking—0.5B ASR may let you reserve VRAM for Qwen harness adapters on the same box.
SiliconANGLE and third-party confirmation
SiliconANGLE on November 18 restates 500M parameters, 40+ languages, and open-weights availability—useful as a secondary check that Reson8's announcement was public, not paywalled. It reiterates Nov 3 API debut versus Nov 18 weights, clarifying two release stages some headlines merge.
If your procurement board asks "is this real?", cite Hugging Face model card + HF blog + Reson8 blog first; outlets second.
Final takeaway for builders
Rumble-2-Flash is worth a weekend bake-off if you pay for multilingual transcription or want on-prem voice before agent stacks. Download Reson8/Rumble-2-Flash, run your audio, compare WER and cost against incumbent APIs, and only then decide whether 0.5B is production or prototype. Open weights shift negotiating power—they do not remove evaluation labor.
For workshop learners wiring voice to agents, explainx.ai's live workshops directory covers agent harnesses separately from model picks; treat this post as the model pick layer only. Revisit Perplexity orchestrator APIs if you need multi-model routing above the transcription step.
Version note: Reson8 labeled Open ASR Leaderboard release 18-11-2026 on the model card; re-run comparisons if leaderboard v1.16.x updates scoring scripts later.
Primary sources: Hugging Face blog, Reson8/Rumble-2-Flash model card, and reson8.dev announcement. Benchmark rows can change when Reson8 updates its public leaderboard exports.
Related reading
If you want to use this at work, not just read about it, this is the fastest path.
- ElevenLabs Kotoba acquisition
- Suno and MiniMax music video tools
- Qwen38 OpenCode harness
- AWS Bedrock agent roadmap
- Maxwell v1 Flash open MoE
- Higher-scoring coding models benchmark debate
Technical claims follow Reson8 and Hugging Face posts dated November 18, 2026.