



Hugging Face says open-model traffic outgrew commercial content delivery networks built for webpages. On November 20, 2026, Julien Chaumond (@julien_c) and Thomas Wolf described a custom CDN moving nearly one exabyte per month of models and datasets.
November 20 volume claims come from Julien Chaumond''s post on X and company reposts; 420 GB/s and 80,000 requests per second come from Thomas Wolf''s post the same day. Architecture context comes from Hugging Face''s official Rearchitecting Hugging Face Uploads and Downloads article, which documented CloudFront limits near 50 GB per file before the custom path matured.
Chaumond wrote that Hugging Face serves almost 1 exabyte of open models and datasets monthly and had to build its own CDN for AI downloads at that scale. He pointed to a live traffic map at huggingface-cdn-live.static.hf.space. Wolf added throughput figures and explained why commercial CDNs misfit giant checkpoint traffic.
TL;DR: architecture shift
 Open weights leaving a release box toward waiting hands, echoing global model pulls
| Old CDN assumption | Hugging Face AI traffic |
|---|---|
| Many small assets | Few giant checkpoint files |
| Human readers globally | GPU clusters in select regions |
| Edge hit ratio over users | Each client wants full file now |
| Cached HTML useful to thousands | Cached 1 TB model useful to few clients, each at line rate |
Wolf''s post adds that caches are adapted to massive objects and release-day mega-floods when trending models and datasets drop together.
Why builders should care
If you ship open weights, your users'' download experience is part of the product. Slow mirrors lose to faster hosts even when benchmarks tie. Hugging Face''s move signals that egress engineering is now frontier work, not only model cards.
Teams running private registries should study:
- Object-size aware cache tiers
- Region pinning near major GPU clouds
- Thundering herd controls when a Llama-class model trends on Hacker News
Our open-weight license guide matters less if nobody can pull the shards.
Relationship to prior Hugging Face security coverage
explainx.ai documented the OpenAI–Hugging Face incident and LASST litigation. CDN design does not replace agent access control, but it shows how central Hugging Face is to open-model distribution.
Claims versus independent measurement
Hugging Face did not attach third-party bandwidth audits in the public posts we reviewed. Independent observers can:
- Compare the live map against their own regional pull tests
- Watch GitHub trending spikes when releases land
- Track cloud provider interconnect bills when mirroring HF hubs
Until audits exist, cite numbers as Hugging Face-stated.
Implications for EU and sovereign AI initiatives
European OVH open-weight MOE and national hubs compete partly on data residency and download latency. A bespoke CDN is a moat: it is hard to clone without Hugging Face''s traffic profile.
Founders pitching sovereign clouds should ask whether they can absorb exabyte-scale monthly fan-out or should peer with HF rather than fork every checkpoint.
Live map and observability
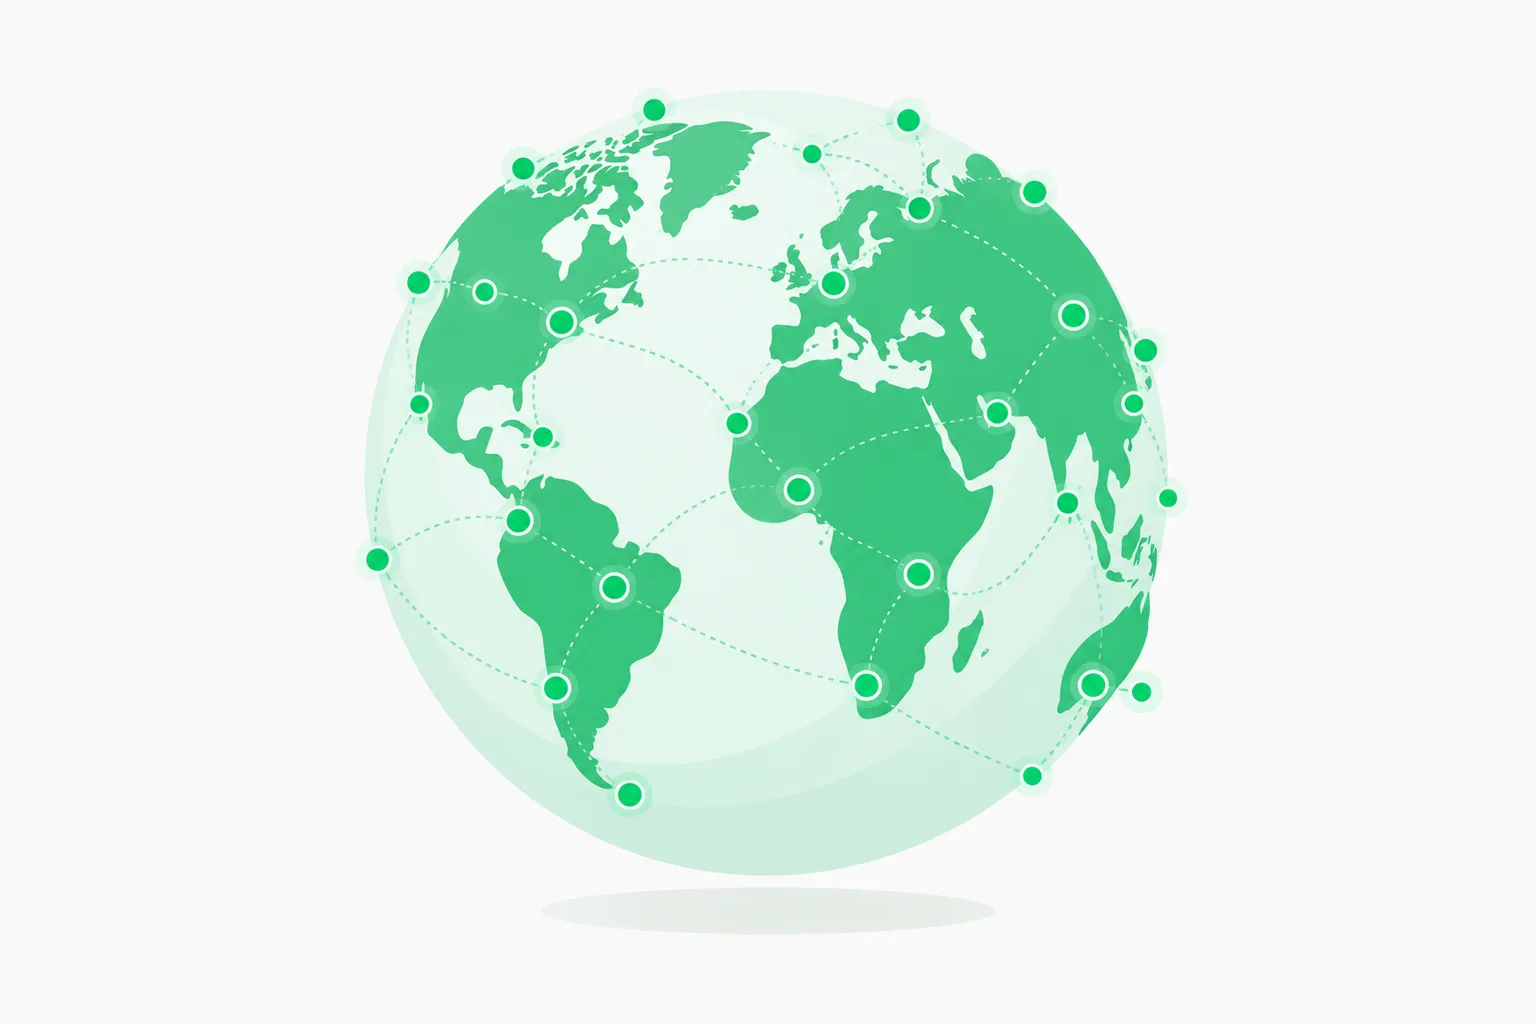 Network nodes on a globe, suggesting distributed CDN traffic
Chaumond highlights the Hugging Face team''s live map as beautiful and hard to stop watching. For SRE teams, that UI is a template: public transparency on cross-border pulls reduces mystery when regulators ask where weights flow.
Pair observability with Together Storage Accelerator style caching products — different layer, same problem class.
FAQ on economics
Does more bytes mean more revenue? Not directly. Hugging Face sells enterprise hub features; exabyte traffic mainly signals strategic importance of open distribution.
Will commercial CDNs retaliate with AI SKUs? Likely, but Wolf argues generic assumptions still mismatch TB-single-object workloads.
Self-host checklist
| Step | Action |
|---|---|
| Size planning | Model peak GB times expected concurrent pulls |
| Cache RAM | Whole-object caches, not fragment-only LRU |
| Release playbook | Stagger shard uploads before social announcement |
| Integrity | Signed manifests; see incident hardening lessons |
| Cost model | Price per full download, not per page view |
How this extends the 2024 Rearchitecting post
The November 2026 messaging is the traffic-scale consequence of changes Hugging Face telegraphed in 2024. The Rearchitecting article explained content-addressed storage, chunk-level uploads, and why CloudFront''s 50 GB object limit conflicted with sharded 70B weights.
Moving to a custom CDN is the download-side mirror: caches must hold entire checkpoint objects and survive synchronized pulls when multiple frontier drops land the same afternoon.
Bandwidth math for practitioners
One exabyte per month is roughly 31.7 PB per day if spread evenly, but ML traffic is spiky. Wolf''s narrative emphasizes release-day mega-floods. Capacity planners should model:
- Peak 420 GB/s as a headline operational rate (company-stated)
- Concurrent 80,000 requests per second mixing range reads and full-file pulls
- Replica count per region high enough that one viral GitHub README does not melt a single PoP
Mirror operators and air-gapped labs
National labs and finance shops often need internal mirrors rather than direct hub access. Exabyte public traffic proves demand; it does not guarantee your VLAN can pull a 400 GB file without change tickets.
Use Hugging Face''s architecture story when arguing for dedicated science networks or on-prem object stores synced nightly rather than per-notebook downloads.
Xet, chunking, and CAS context
Hugging Face''s Xet storage work targets deduplicated chunk uploads. Large models already arrive as 20 GB shards per the 2024 engineering post. A custom CDN must align with CAS reconstruction so clients do not re-download unchanged chunks after a minor adapter release.
If your hub product wraps Hugging Face, expose revision-aware pull to customers so they do not repeat full exabyte-scale mistakes internally.
Environmental and power narratives
Exabyte traffic has energy implications even when weights are open. Pulling a trillion bytes repeatedly burns interconnect and disk lifecycle budget. Pair download policy with IEA data-center outlook planning — not because Hugging Face caused a specific outage, but because bits moved are power moved.
Competitive landscape
Closed labs distribute weights through private agreements; Hugging Face competes on frictionless HTTP pulls. Custom CDN is moat infrastructure similar to how cloud GPU financings shape who can train, but here the scarce resource is egress engineering talent.
When commercial CDNs still fit
Small adapters under a few gigabytes may remain fine on commodity CDNs. Wolf''s argument targets frontier checkpoints and dataset tarballs that break classical assumptions. Do not overcorrect and rip out CloudFront for your marketing site while only models needed the bespoke path.
Developer FAQ on downloads
Will huggingface-cli automatically use the new CDN? The November leadership posts describe infrastructure behind the Hub, not a mandatory CLI flag change. Expect transparent routing for most users.
Does the live map expose private repos? The map visualizes aggregate traffic, not per-account filenames. Still treat any public telemetry as marketing-grade, not a security audit log.
Should I pin revisions? Yes. Exabyte-scale re-pulls hurt when teams float on main without commit hashes. Pin revision in training configs the same way you pin Docker digests.
Incident response tie-in
If a malicious shard ever poisons a mirror, fast rollback requires immutable revision IDs plus mirrored checksums. Read the OpenAI–Hugging Face technical report timeline for how quickly agent paths scaled when guardrails failed — delivery speed and security speed must be designed together.
Cost conversation for CFOs
Egress bills at exabyte scale dominate unit economics for free open weights. Hugging Face subsidizes distribution as strategic spend; your startup probably cannot. Model hosting startups should quote customers per-terabyte pulled, not flat SaaS seats, when files exceed 100 GB.
Regional fairness
Chaumond''s map highlights global pulls. Teams in bandwidth-constrained regions may still see latency; custom CDN does not magically add last-mile fiber. Consider OVH European MOE style regional mirrors for sovereignty requirements.
SRE runbook sketch
On release day, assign an owner to watch the live map, hub error rates, and GitHub issue velocity. Pre-warm mirrors in us-east, eu-west, and ap-southeast regions if your org blocks cross-border pulls. Document median time-to-first-byte before and after the drop so leadership sees infrastructure as a product surface, not a footnote.
Legal and licensing reminder
Open weights remain subject to license terms regardless of how fast bytes move. Exabyte distribution makes license violations scale too — a forbidden fork spreads as quickly as a permitted one. Keep open-weight license explainers in onboarding docs for every engineer with huggingface-cli access.
Benchmark for your platform team
Run an internal table exercise: list your ten largest artifacts, their gigabytes, expected concurrent pulls, and whether your CDN contract bills per request or per byte. If any column looks like Hugging Face''s public description — huge objects, few regions, machine clients — negotiate dedicated cache tiers now instead of after your first viral model release.
Partnerships with cloud GPU financiers mean little if customers cannot pull weights when a cluster is ready. Treat download SLOs as part of the same executive dashboard as tensor FLOPs.
Document median time-to-first-gigabyte in your public status page if you compete with Hugging Face for open-model hosting; transparency builds the same trust Chaumond pitches with the live map. Revisit the number after each major base-model drop and after each regional cache expansion starting today.