



Amazon Web Services on November 20, 2026 published an Agent Toolkit skill that lets coding agents evaluate and deploy distributed KV caching for self-hosted vLLM and SGLang fleets. The problem is familiar: each GPU server keeps an isolated prefix cache, so a user who resumes a long agent thread on another node pays full prefill again. AWS says Amazon ElastiCache for Valkey can hold a shared L2 tier beside the GPU fleet, with cited benchmarks up to 40% inference cost reduction and 80% faster time to first token (TTFT) when prompts repeat above a length cutover.
If you run vLLM vs SGLang comparisons on p5 instances, this skill is AWS’s guided path from diagnosis to LMCache wiring—not a new inference engine, but agent-operated infrastructure setup.
TL;DR
| Step | What the skill does (AWS blog, Nov 20, 2026) |
|---|---|
| Fit check | Read-only EC2 describe; count EFA; gather model, TP size, KV dtype, routing |
| ROI gate | Run KVTrace on your traffic; stop if savings do not cover cache nodes |
| Sizing | Example: two cache.i8ge.48xlarge nodes for eight p5 hosts on 64K legal prompts |
| Engine hook | Add LMCache connector to existing vLLM/SGLang, including llm-d and Ray Serve workers |
| Consistency | Force one KV ID hash mechanism and explicit KV dtype across servers |
| Validation | Empty local tiers; verify two cache-loaded runs match before production |
| Agents | Works with Claude Code, Codex, Kiro, other Agent Skills hosts |
Why isolated GPU caches waste money
AWS opens with a legal assistant example: hundreds of thousands of tokens of case history per conversation. When the attorney returns after lunch, the GPU that picks up the session has no KV state for that transcript. The model recomputes attention keys and values for every prior token—prefill—before generating a single new word. The same pattern hits coding agents, document Q&A, and any multi-turn agent harness that resends full context each turn.
Local prefix caching on one server only helps when session affinity keeps the user on that host. Routing shifts, autoscaling, and failures break affinity. Distributed KV caching stores reusable KV blocks in ElastiCache so any inference worker can RDMA-load them.
What the Agent Toolkit skill automates
AWS built the skill so a coding agent can run the workflow in conversational steps:
-
Fit check before spend — describe-instances, EFA count, and questions the API cannot answer (engine, tensor parallel size, KV dtype, server price, prompt repeat rate). The agent must stop when constraints fail.
-
KVTrace ROI — offline replay of cache events without deploying cache hardware. AWS stresses traces contain hashes and counts, not prompts, with optional
--anonymize-key-file. -
LMCache integration — patch existing vLLM or SGLang stacks, including workers under llm-d and Ray Serve, without replacing routing logic.
-
Guardrails — matching KV ID seeds and dtypes to prevent key mismatch (healthy hit counters with wrong answers). Production promotion requires explicit human approval for create/change/delete operations.
The skill ships from the Agent Toolkit for AWS with the AWS MCP Server—the same pattern as other agent skills teams mount in Claude Code.
Flow 1: Diagnosing slow first token
AWS’s sample prompt: a vLLM fleet serving 64K-token legal contexts on p5 instances with 13-second TTFT because the GPU recomputes history every turn.
The agent identifies cold prefill, checks whether enabling prefix caching alone fixes back-to-back turns, and flags tenant isolation: shared caches can leak timing signals between tenants. AWS recommends separate caches or tenant-specific KV hash salts when cases must stay isolated.
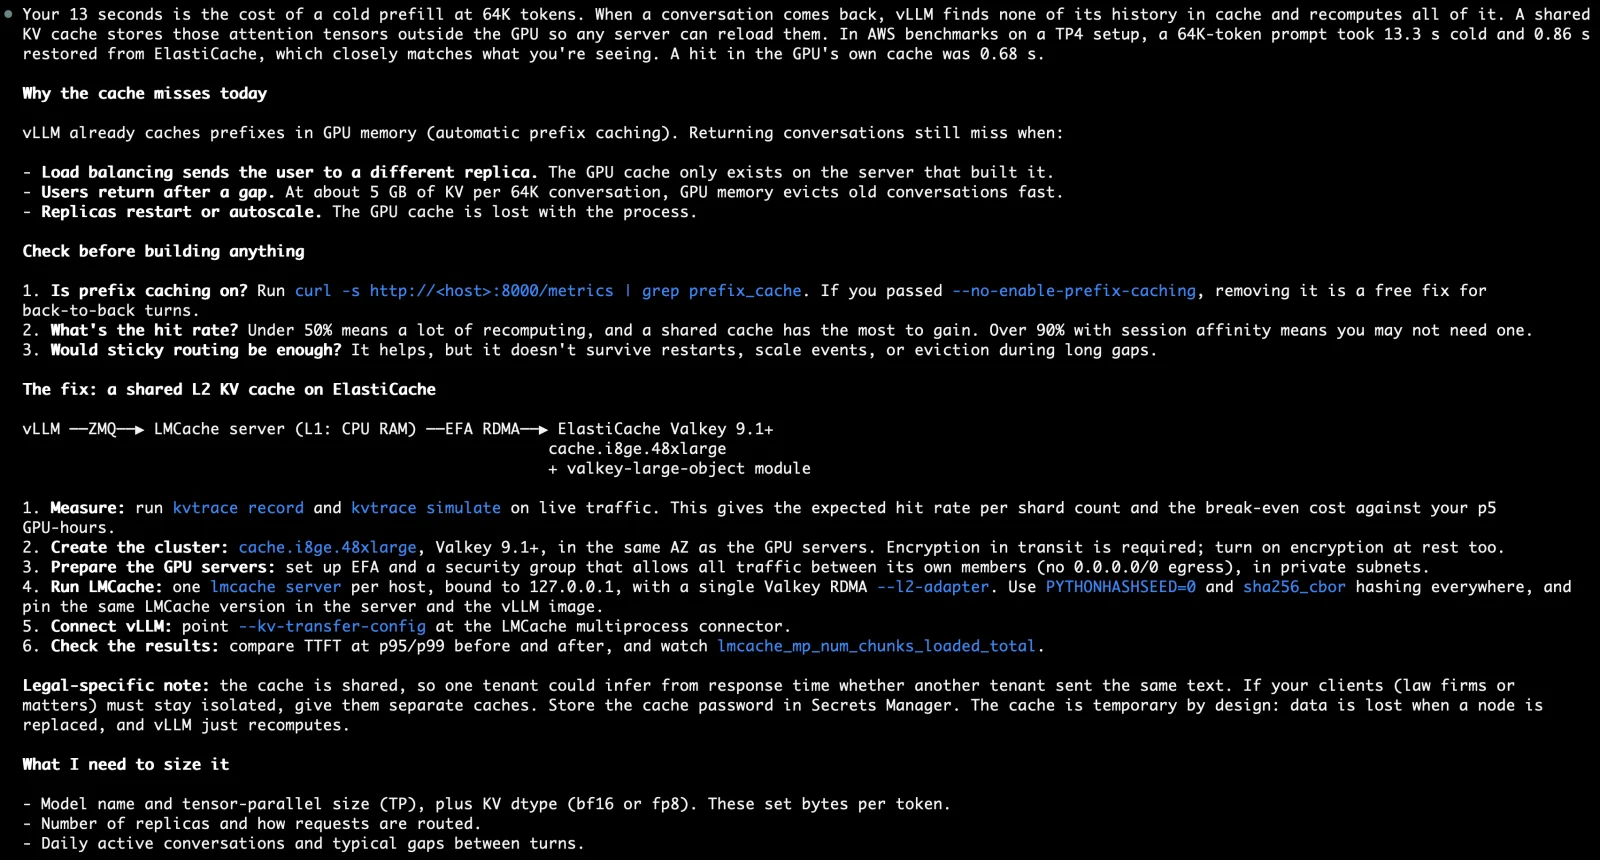 AWS distributed KV caching agent skill diagram for legal assistant GPU fleets
Image: Amazon Web Services
Flow 2: KVTrace savings estimates
For eight p5 instances and 64,000-token RAG prompts, the blog’s agent looks up GPU and cache node prices, derives prefill throughput and KV bytes from benchmarks, and proposes two cache.i8ge.48xlarge nodes.
When the operator omits a cache hit rate, the agent shows scenarios and recommends a KVTrace run. KVTrace replays recorded events against candidate cache sizes and recommends the smallest capacity that reaches 90% of the savings ceiling in AWS’s synthetic demo report.
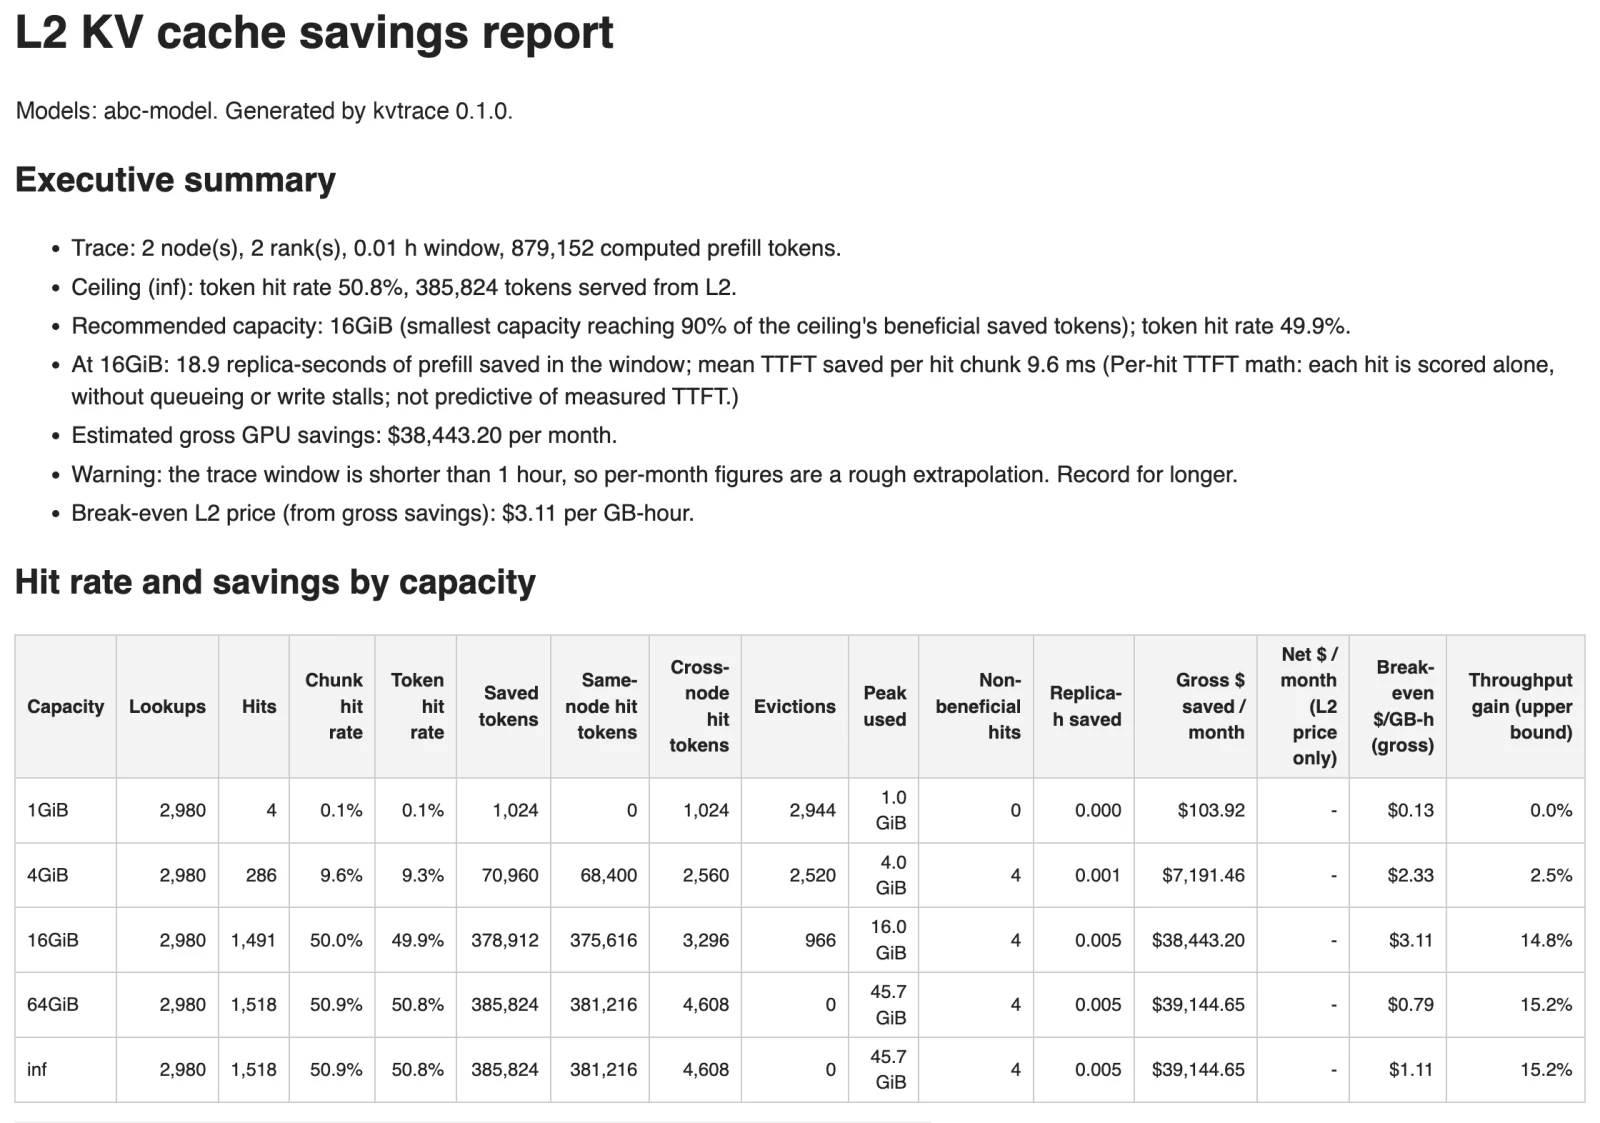 KVTrace report chart for distributed KV caching cost savings on self-hosted LLMs
Image: Amazon Web Services
AWS also notes freed GPU cycles only become dollars if you scale down servers or serve more traffic on the same fleet—an easy mistake in capacity planning.
Flow 3: Standing up ElastiCache Valkey
On confirmation, the agent creates security groups with EFA permissions, a Valkey 9.1 cluster with eviction-tuned parameter groups, LMCache cache users with Secrets Manager passwords, and per-GPU LMCache servers. Health checks use small test objects and repeated prompts to confirm RDMA loads from ElastiCache.
Detailed commands live in Amazon ElastiCache distributed KV caching documentation.
Flow 4: Troubleshooting RDMA errors
AWS’s troubleshooting prompt: LMCache connects and BLOB.RDMA_HELLO succeeds, but INFO largeobj shows climbing rdma_write_errors. The skill points to security groups that block EFA traffic between members, with CLI steps to inspect and fix rules—exactly the class of failure that shows up when agents automate infra without network diagrams.
Prerequisites checklist
| Requirement | Version or SKU (per AWS post) |
|---|---|
| Coding agent | Agent Skills support (Claude Code, Codex, Kiro, etc.) |
| GPUs | p5 or other EFA RDMA write instances |
| LMCache | 0.5.8rc1+ |
| vLLM | 0.11.1+ |
| SGLang | 0.5.13+ |
| ElastiCache | Valkey 9.1+ on cache.i8ge.48xlarge |
How this fits the inference stack landscape
Distributed KV caching is complementary to:
- SageMaker HyperPod Global Inference Gateway routing across regions—caches must stay co-located with GPU pools they serve.
- Enhanced observability for bad GPUs—slow nodes look like cache misses if not separated in metrics.
- NVIDIA training failure diagnostics—orthogonal to inference prefill, but the same fleets often run both.
Teams on Together serverless pricing or hyperscaler APIs may skip self-hosting entirely; this skill targets operators who already pay for p5 capacity and need agent threads to stop recomputing million-token contexts.
Cutover math: when cache beats recompute
AWS’s blog stresses a cutover point in prompt length: below it, reading KV blocks from ElastiCache can take longer than recomputing attention on-GPU. Above it—and when the same prefixes repeat across sessions—shared L2 wins. Legal, coding, and support bots with static system prompts plus growing user threads usually sit above that threshold faster than single-shot Q&A.
The skill forces the agent to cite where each number came from (price list lookups, benchmark-derived prefill rates, KVTrace scenarios). That matters because vendors sometimes market cache products with fleet-wide averages that hide low-repeat traffic segments. Run KVTrace on a full business day per AWS’s guidance before approving cache.i8ge nodes.
Operational checklist before production traffic
- Harmonize dtypes and hash seeds across every vLLM worker—including Ray or llm-d sidecars.
- Drain local tiers and run duplicate prompts; mismatched tensor layouts can pass health checks yet change outputs.
- Measure L2 hit share against KVTrace prediction after the cluster is live.
- Document tenant isolation decisions if multiple customers share one GPU fleet.
- Keep prefix caching enabled where session affinity is high; distributed cache complements rather than replaces on-box caches.
Security and tenancy notes
AWS explicitly warns that shared KV caches can let one tenant infer another’s repeated text from timing unless you shard caches or salt hashes. For regulated workloads, treat cache tiers like PCI-scoped Redis: separate clusters per tenant class, audit RDMA security groups, and rotate Secrets Manager passwords LMCache users consume.
Agent skills that create cloud resources should stay behind human approval gates—the skill’s design asks the agent to request confirmation before creating billable ElastiCache nodes.
Related reading
- vLLM vs SGLang inference server comparison
- Amazon SageMaker HyperPod Global Inference Gateway
- What is MCP?
- Claude Code commands reference
- Loop engineering for coding agents
- Streaming DiLoCo and MaxText TPU training
How to start the skill in your agent
AWS tells operators to pull the skill from the Agent Toolkit for AWS repository or install the AWS MCP Server, then describe the latency problem in natural language (for example the 13-second legal-assistant TTFT example). The agent should load the skill only after approval in environments like Kiro.
Pair the skill with your existing observability: track TTFT p50/p95 and GPU prefill seconds before and after cache enablement. Without those baselines, finance teams cannot verify AWS’s 40% cost headline on your fleet.
If you already run SageMaker HyperPod across regions, deploy cache clusters per GPU pool—cross-region KV reuse is not described in the November 20 post.
When to skip ElastiCache entirely
Stay on single-node prefix caching when:
- Sessions stick to one GPU with greater than 90% prefix hit rate already.
- Median prompts stay below the KVTrace cutover for your model width.
- Traffic is mostly unique one-shot queries with no repeated system prompts.
- Regulatory policy forbids shared cache tiers between customers.
The skill is designed to stop early in those cases rather than provision cache.i8ge hardware by default.
Sources
Primary: Cut self-hosted LLM cost and latency with the distributed KV caching agent skill (AWS ML Blog, November 20, 2026).
Technical companion: Announcing distributed KV caching for self-hosted LLMs with Amazon ElastiCache.
Specifications and versions are accurate as of November 21, 2026.